A finding is only useful if you can prove it.
Inspect an agent’s attack surface, the vectors behind its exposure and where each finding stands.
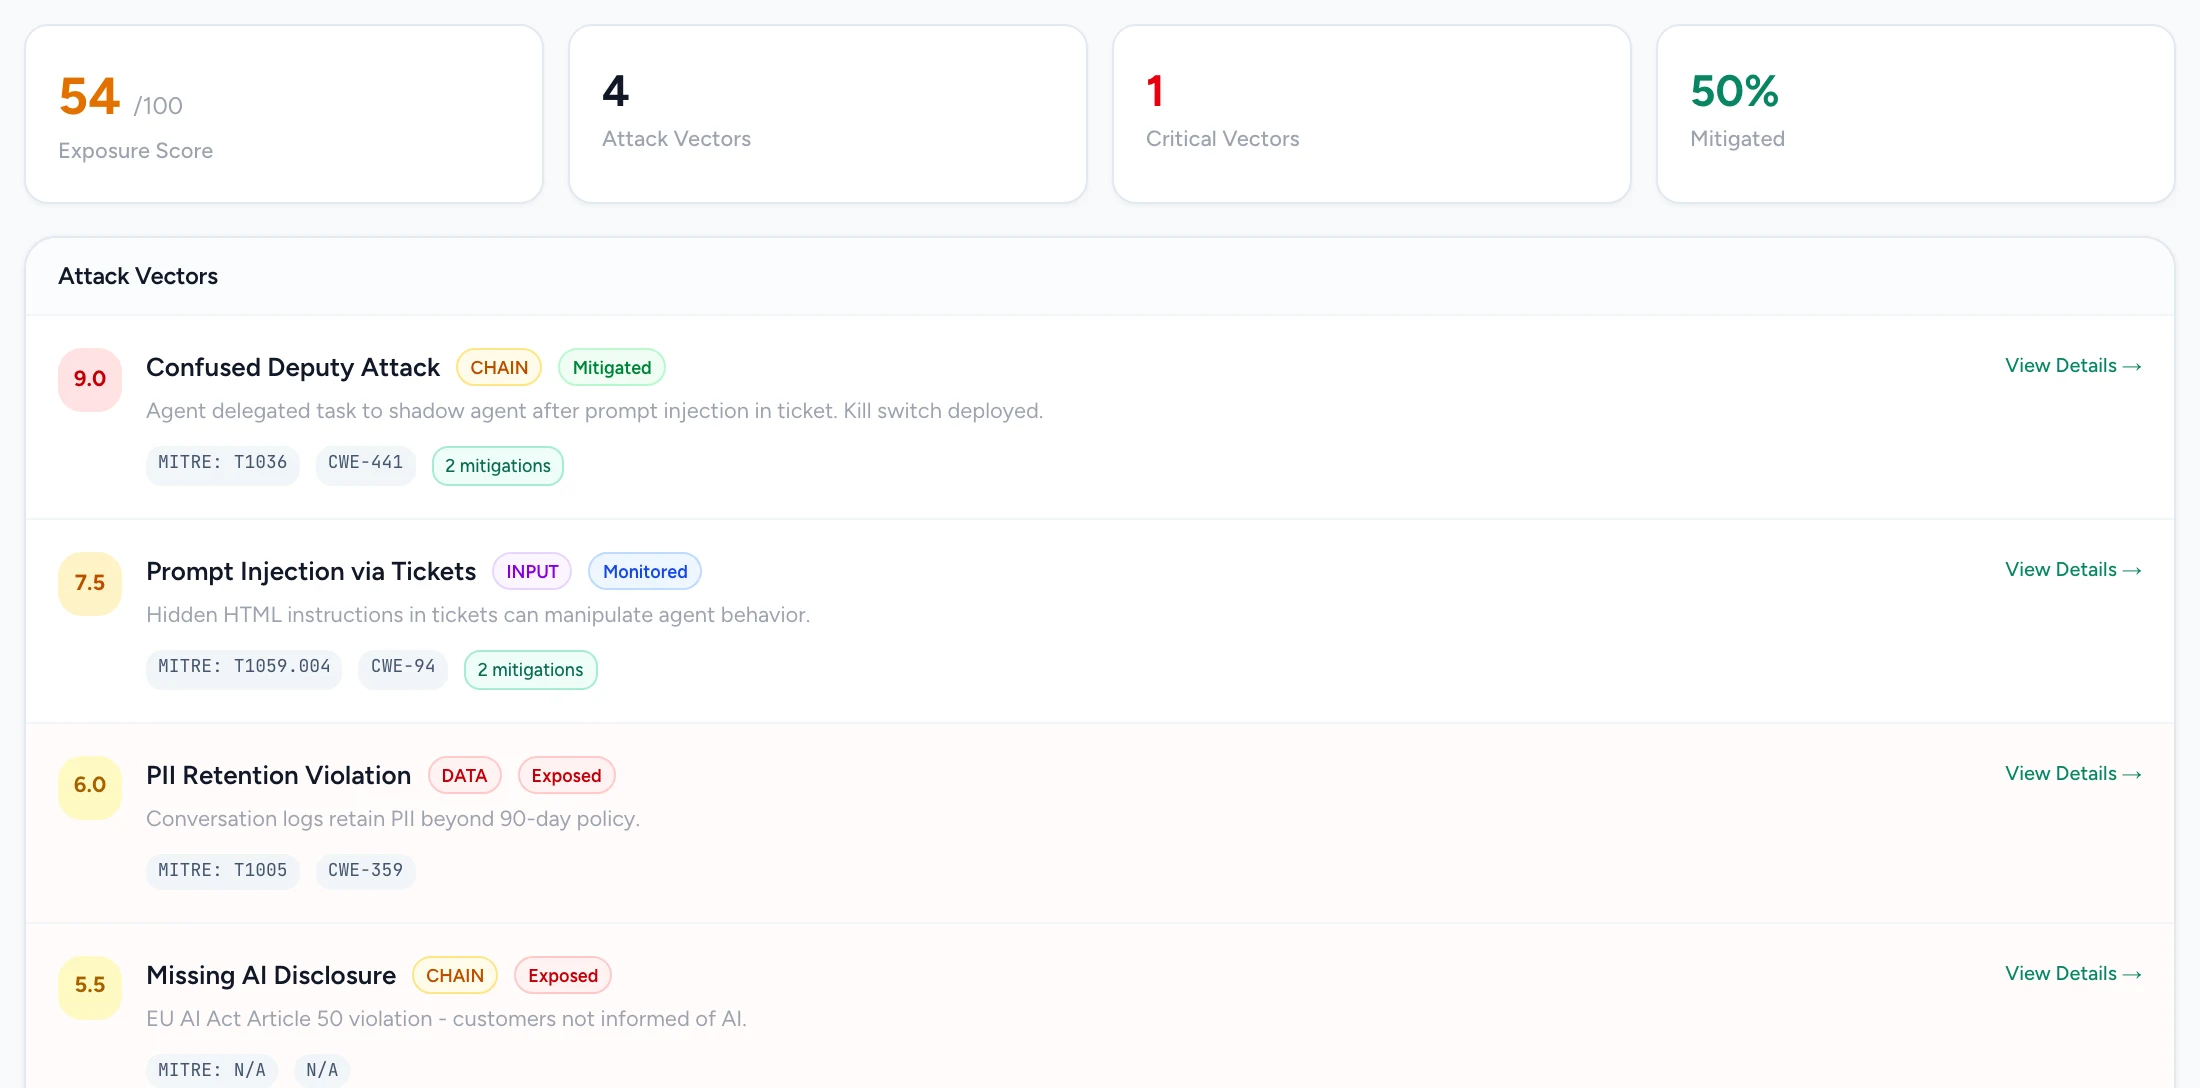
Scroll the image to inspect the details.
Wherever an agent takes input, it can be tested.
Tested through the platform’s own API.
quote-approval-helper can be tested through the Copilot Studio API. It had never been tested, and the plan Guard0 chose from its scopes runs in one click.
More on Platform & SaaS agents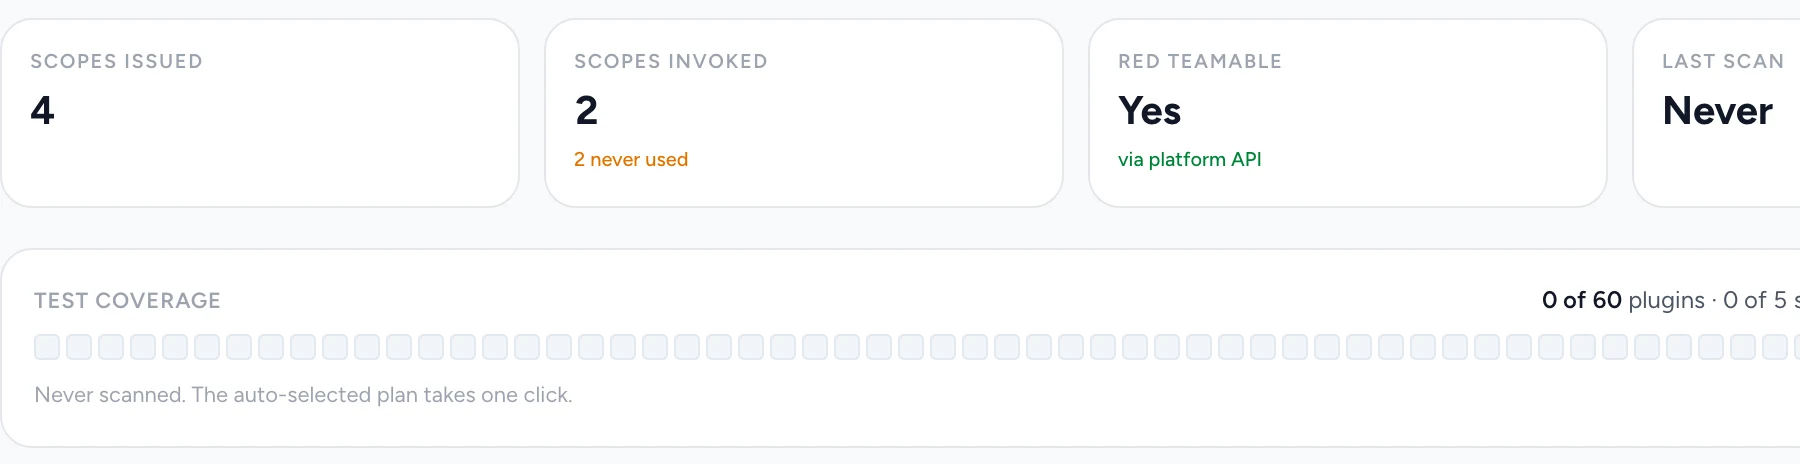
Scroll the image to inspect the details.
We ran 196 evaluations across 68 models and published the results, with the method.
Attack, prove, fix, retest.
- The attacks agents face
- Prompt injection through tickets and documents, tool misuse, data exposure and confused deputy chains, across 25 attack categories.
- Adaptive and multi-turn
- Tests change course across turns, the way a person probing an agent would.
- Findings with proof
- The payload, every tool call, and MITRE ATLAS and CWE references, routed to the agent’s owner.
- Retest after the fix
- The same payload runs again, and the finding closes only when it passes.
Common questions
Can you red-team agents inside Copilot Studio or Agentforce?
Yes, through the platform’s own API, with the same attack library that runs against the agents you build.
Does testing touch production?
You choose the target. Tests run against staging or the platform’s test interface.
How do findings map to frameworks?
Each finding carries its MITRE ATLAS and CWE references and maps to the OWASP Top 10 for LLM applications and the OWASP Agentic Top 10.
Start with one agent.
Pick an agent, run the plan Guard0 chooses for it, and read the findings the same day.